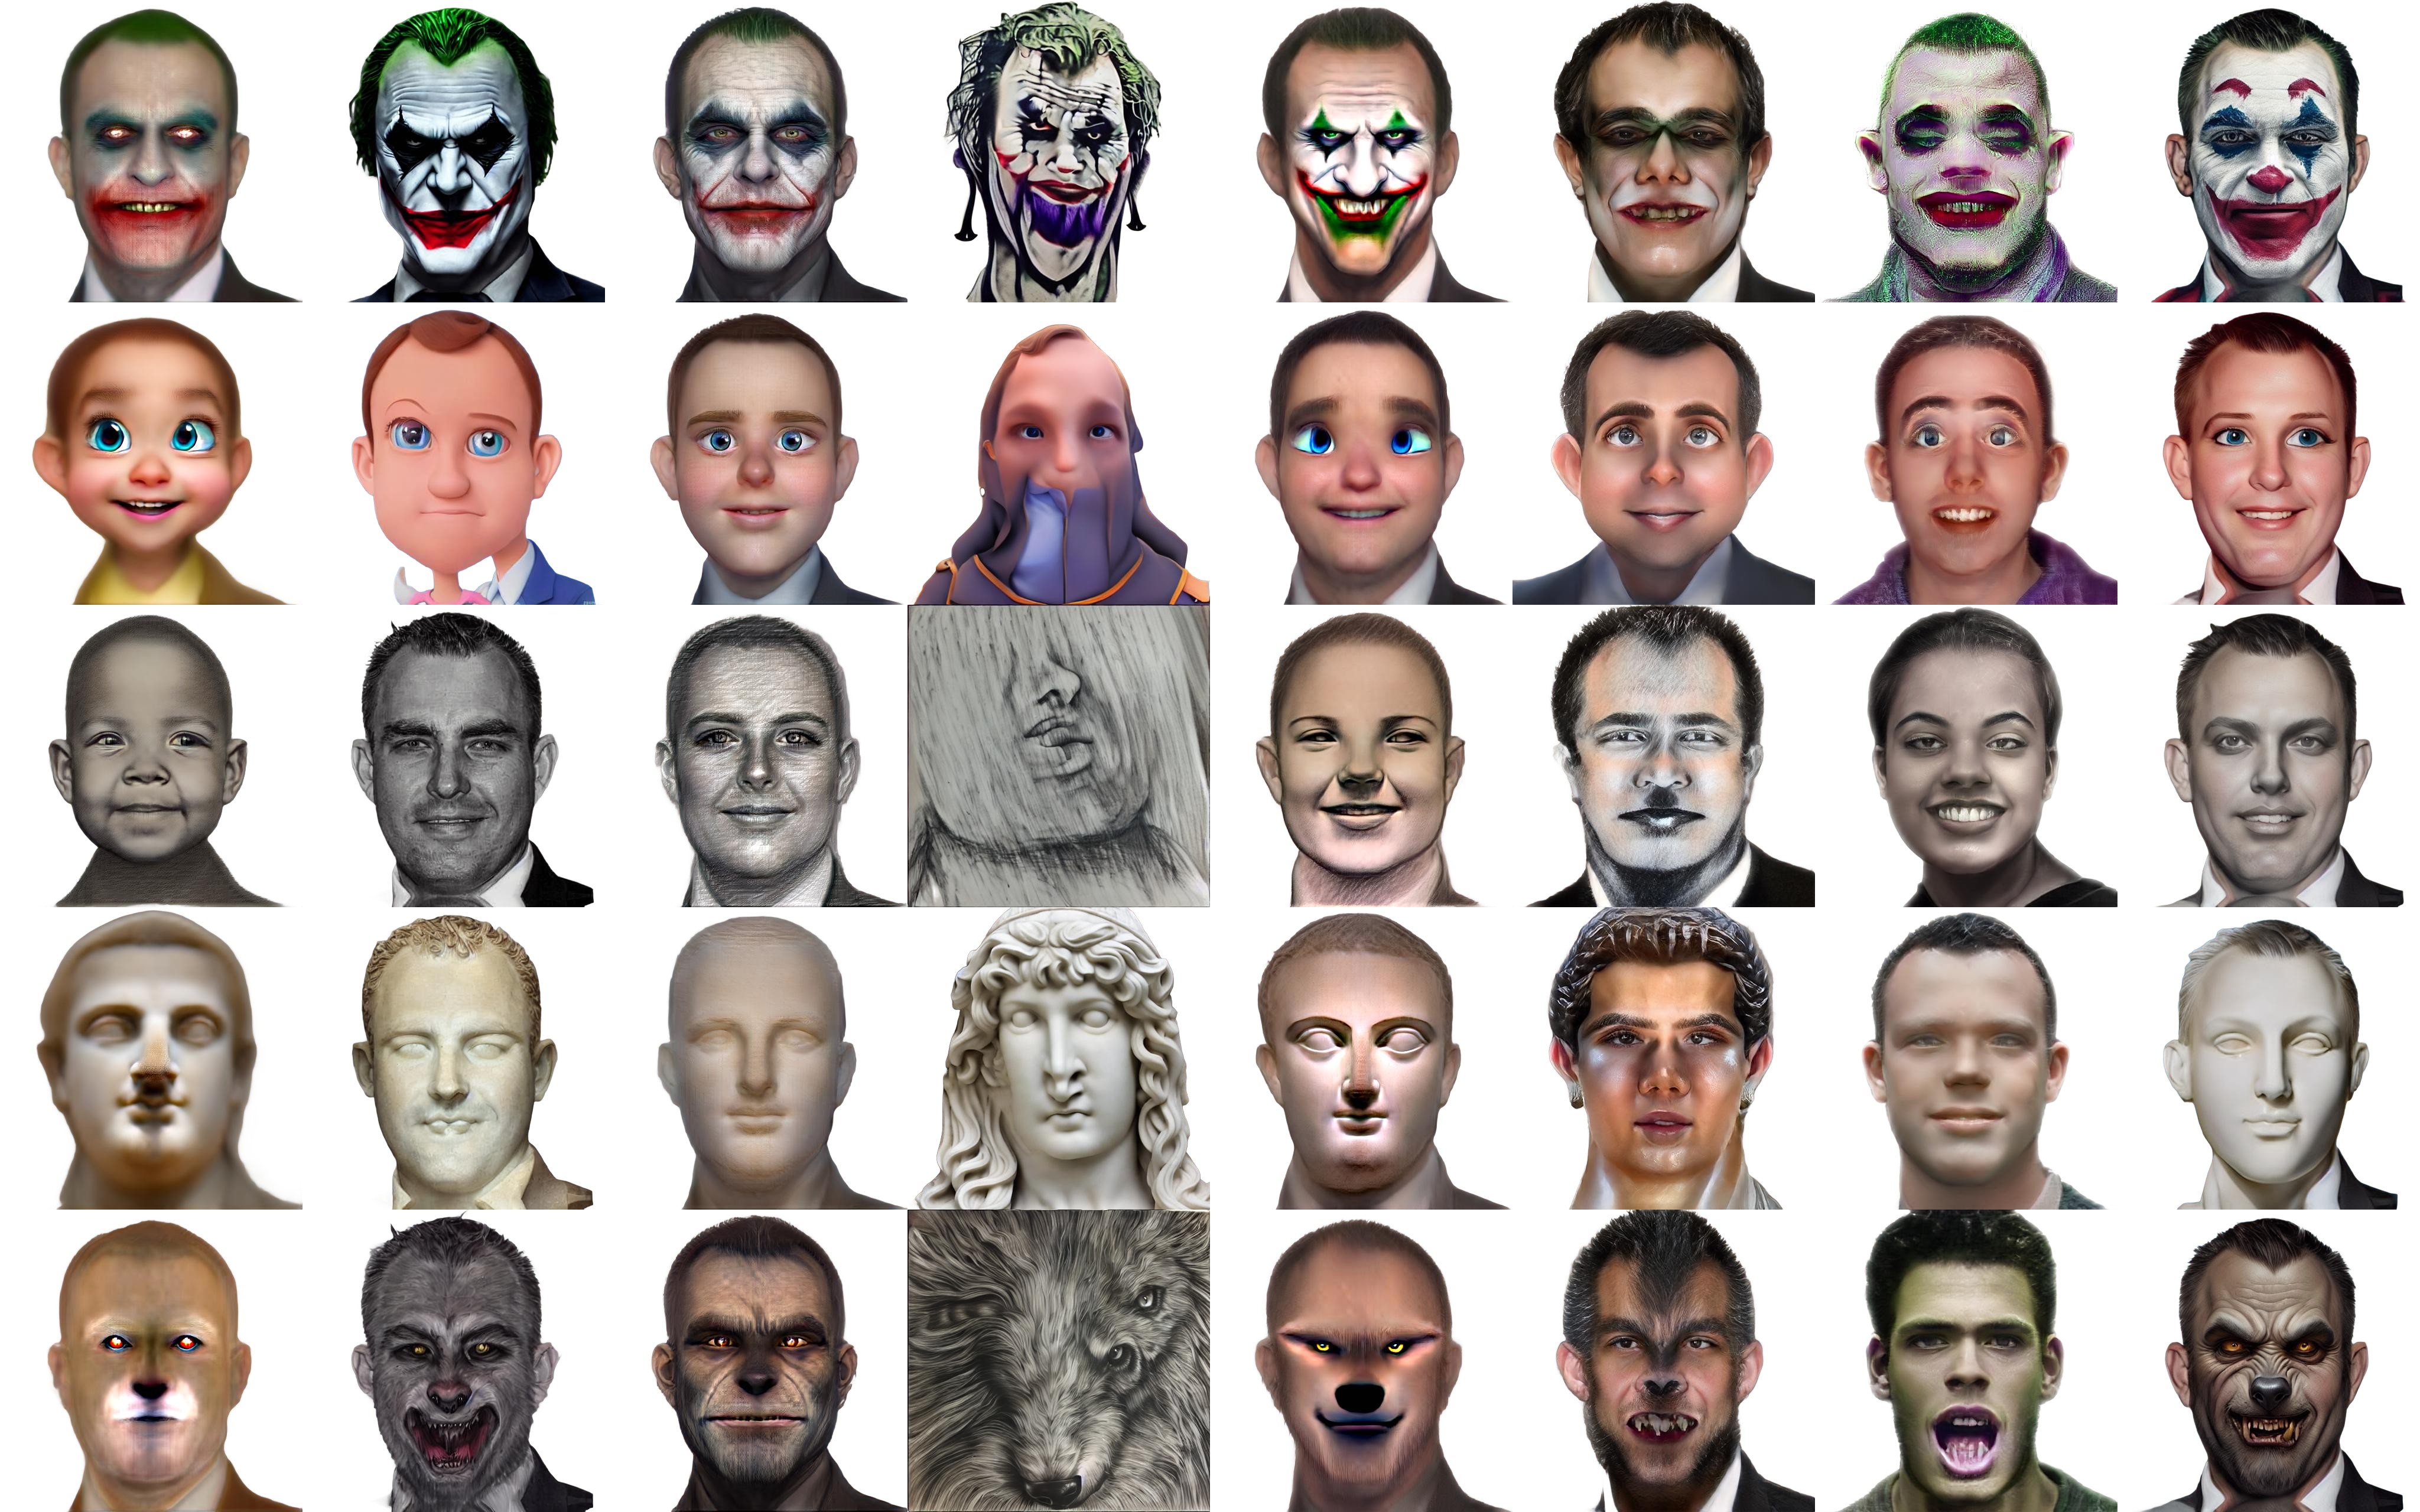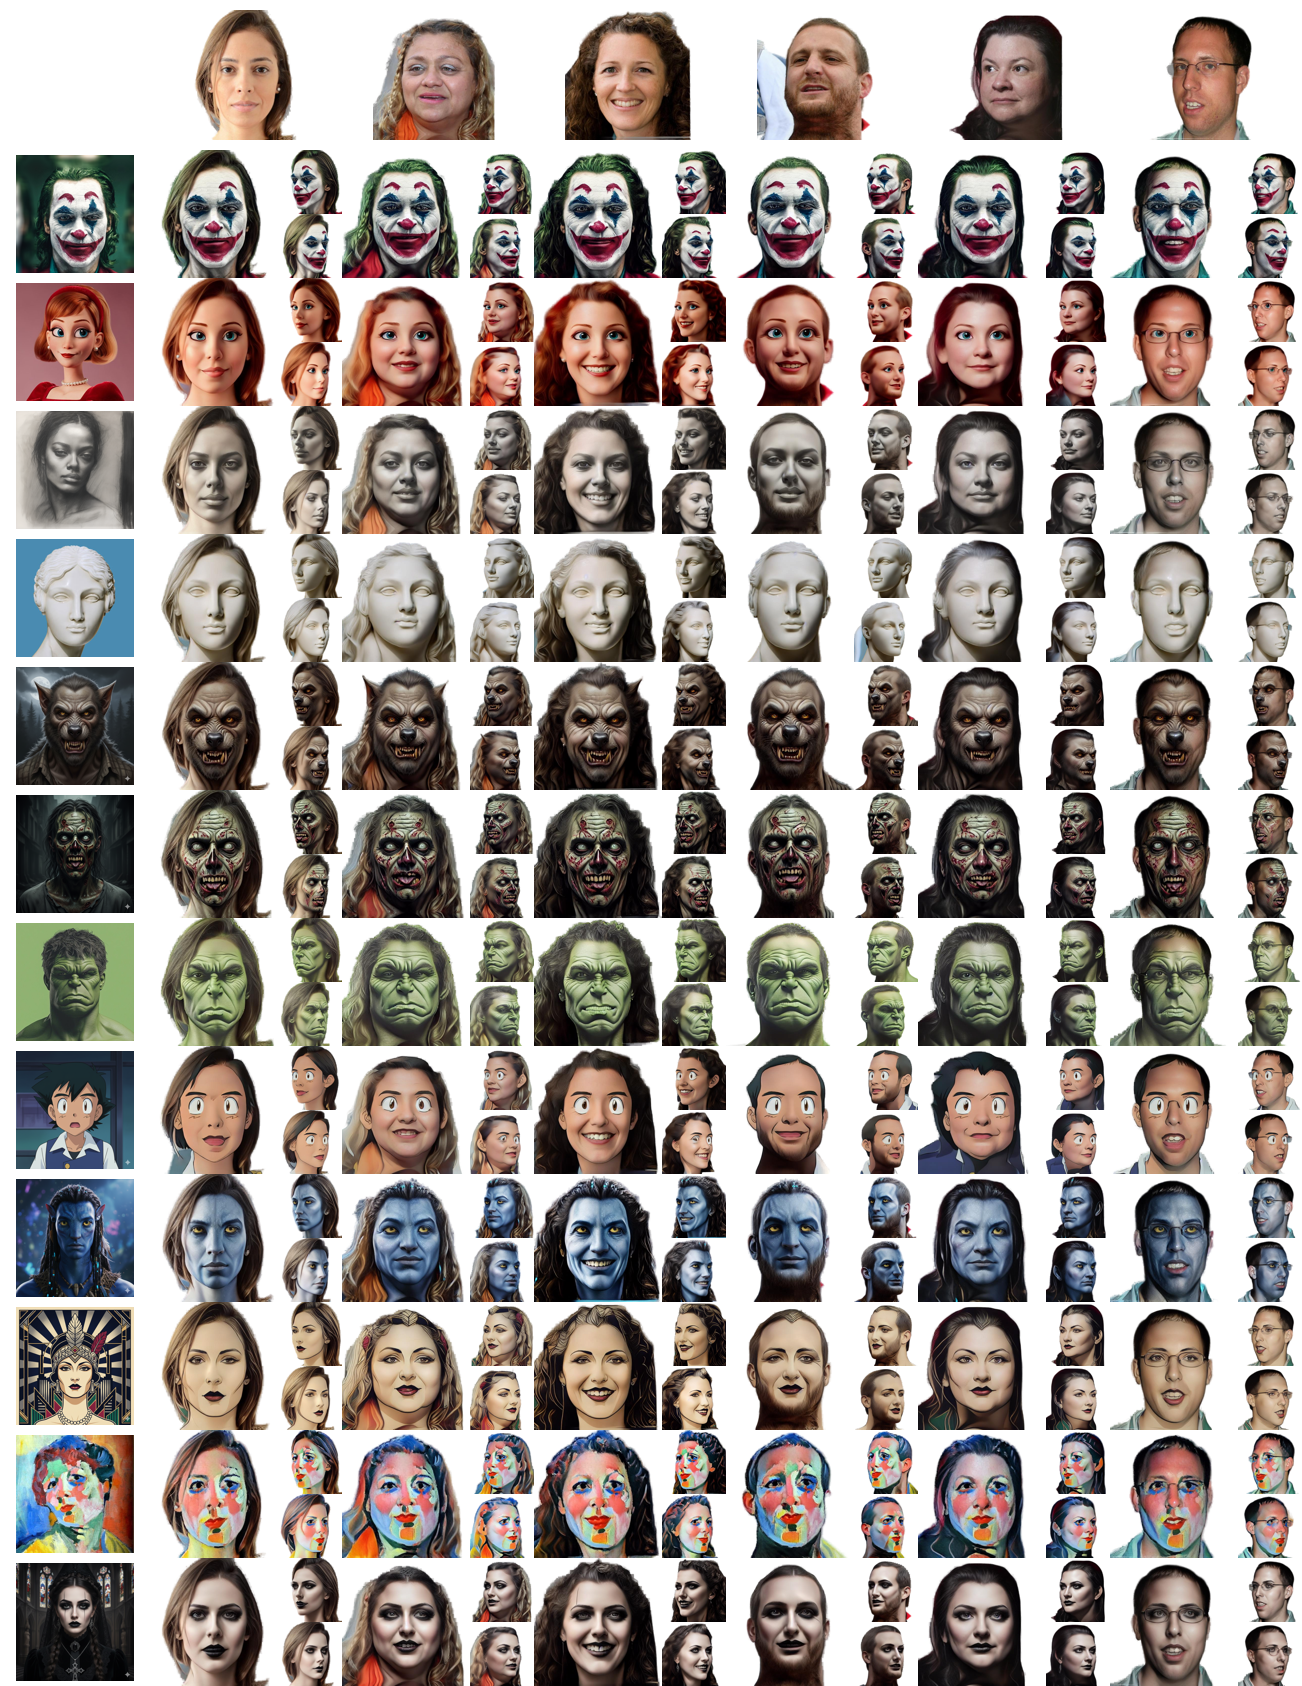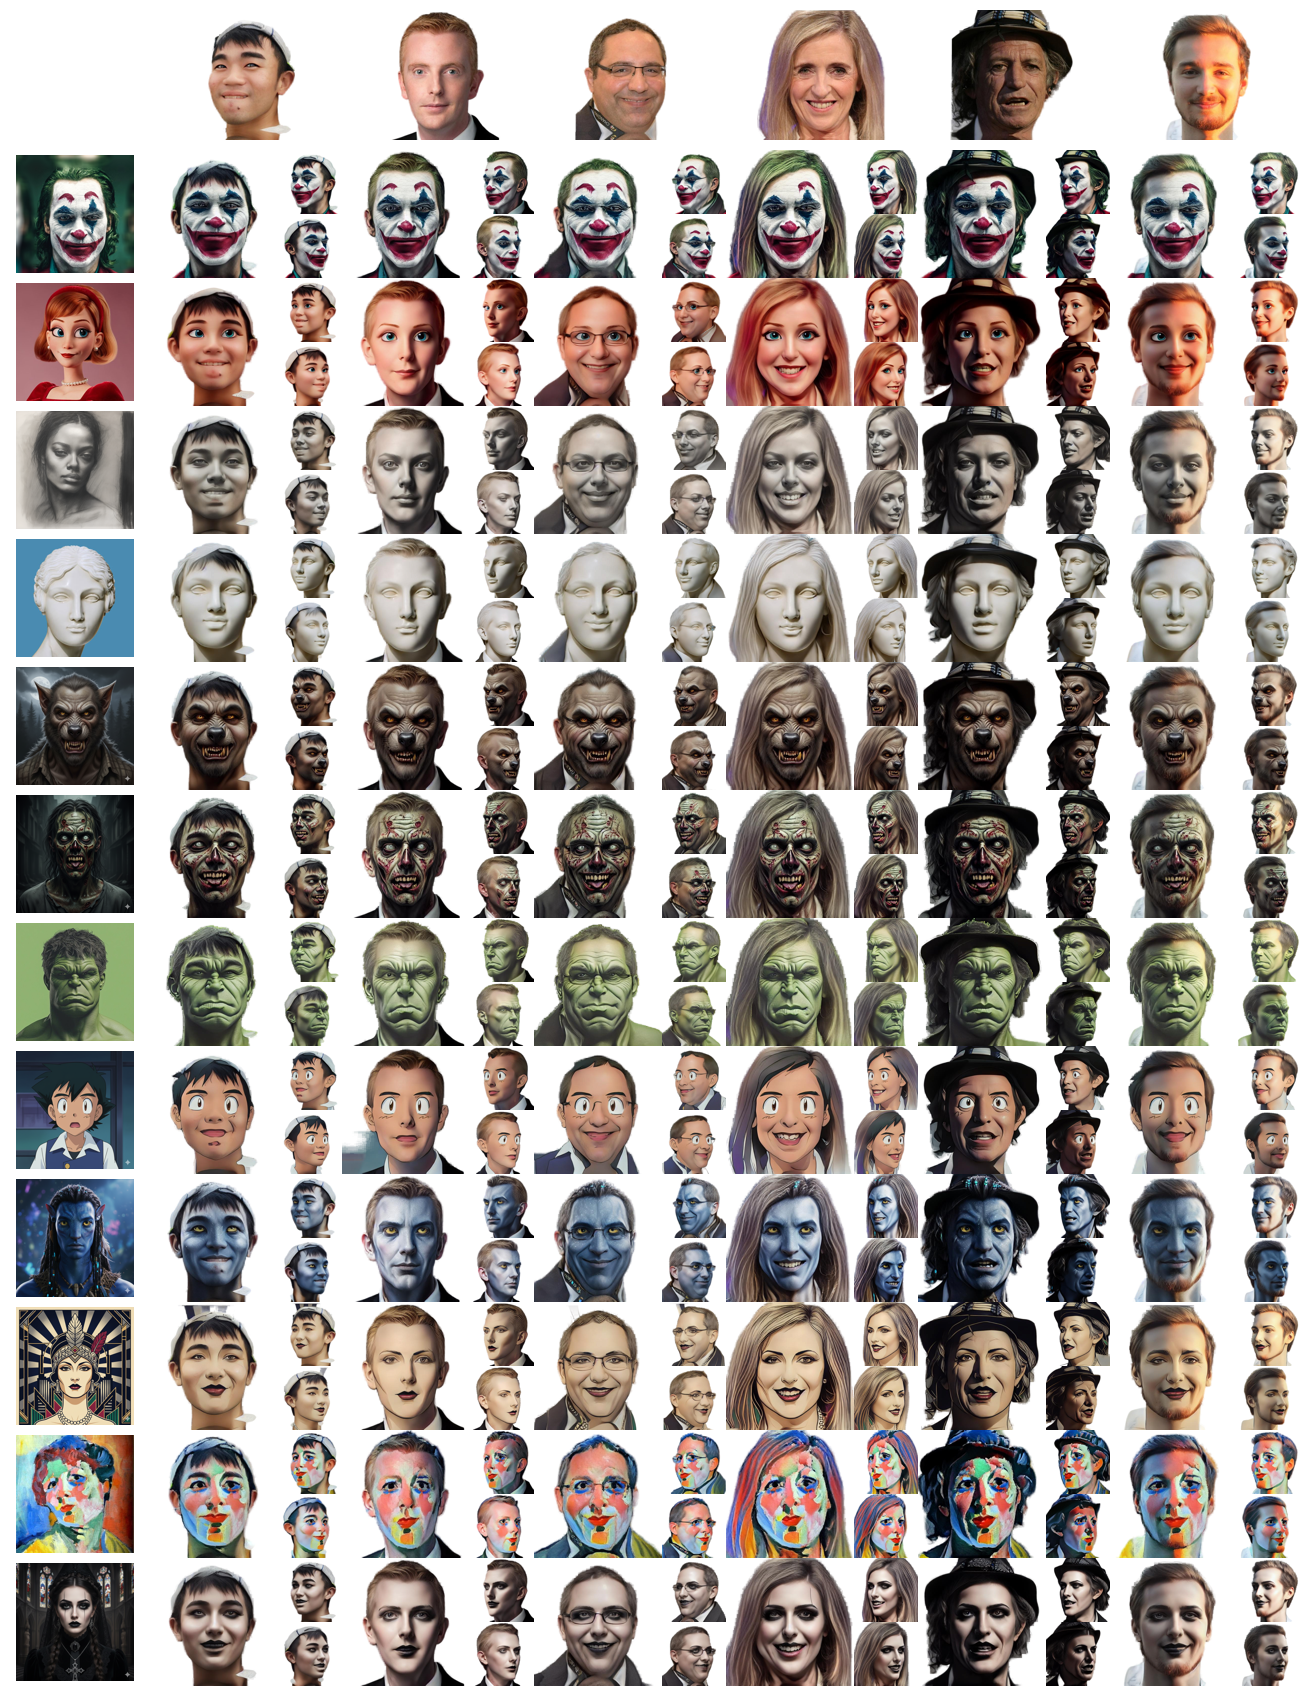
Our method generates identity-preserving and multi-view consistent stylizations across diverse artistic styles, including cartoon-like and realistic domains. StyleFusion360 preserves fine attributes such as accessories, facial expressions, and head geometry while achieving high style fidelity without requiring per-style retraining.
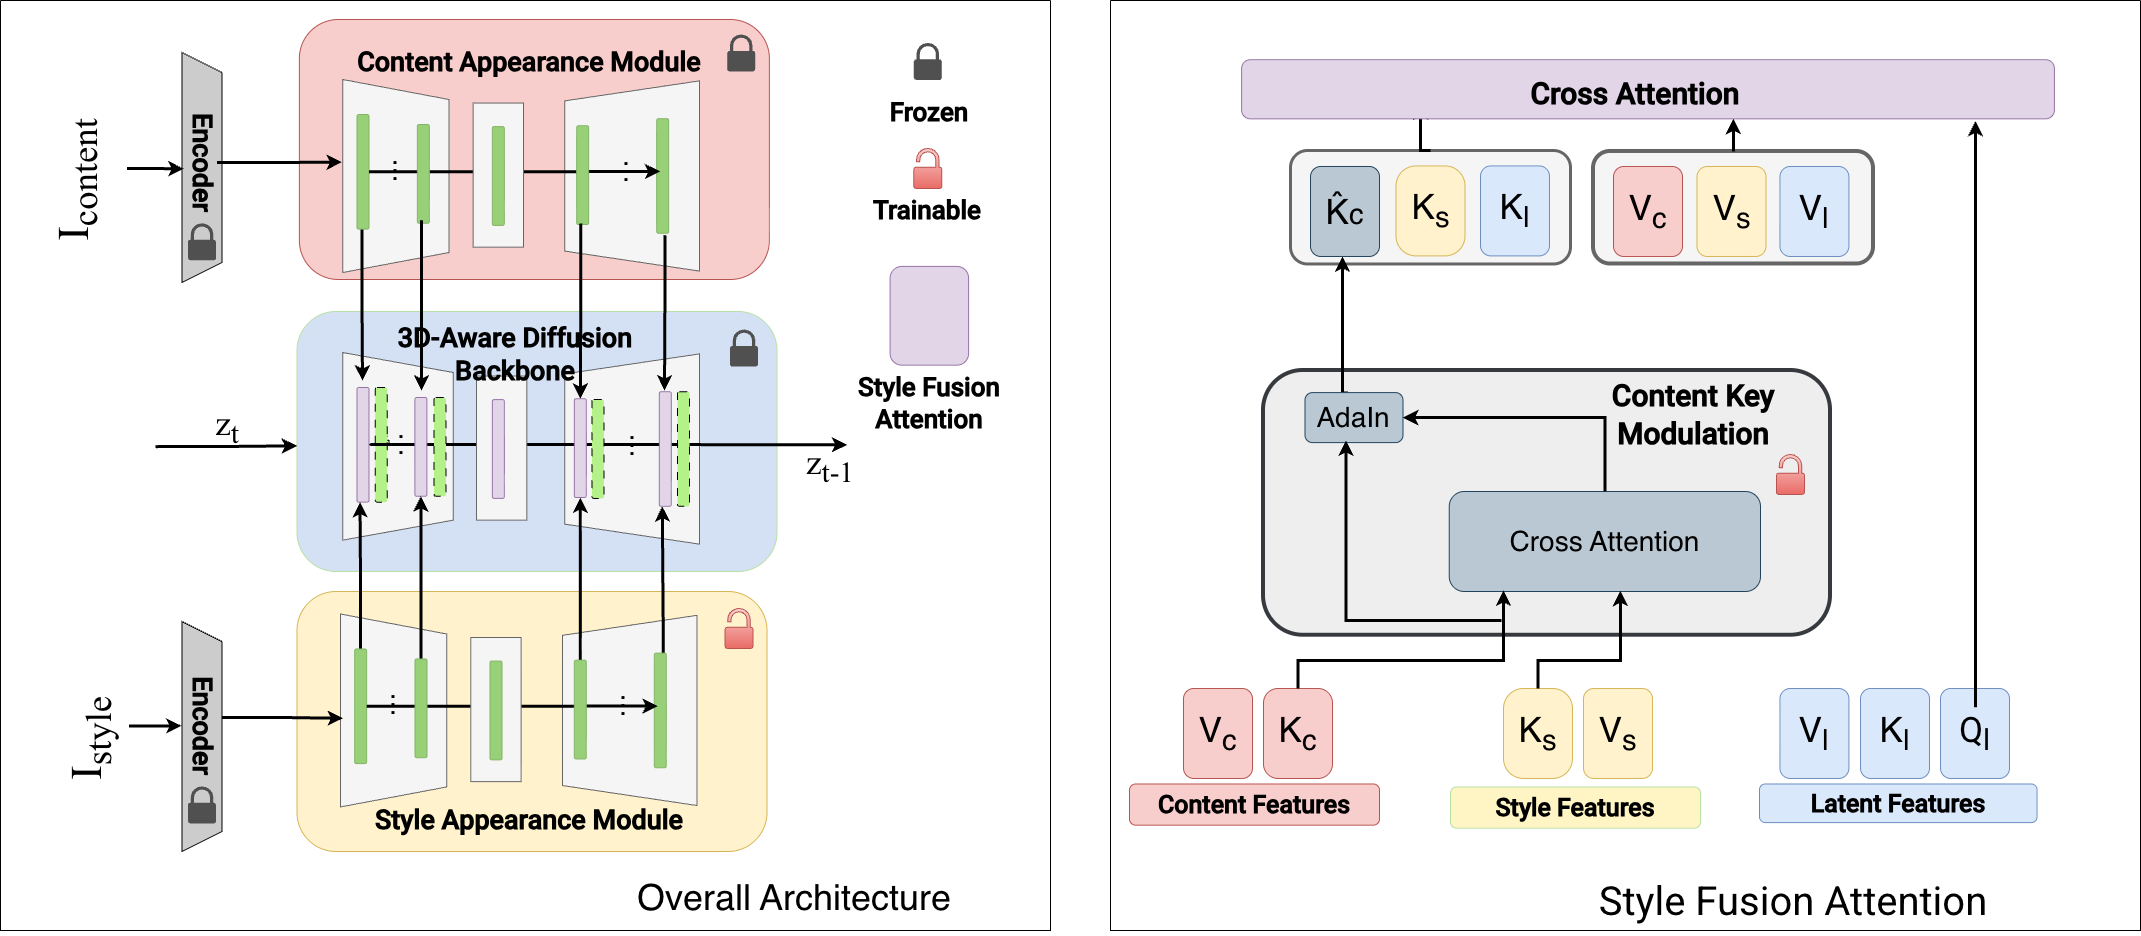
StyleFusion360 is a diffusion-based framework for multi-view consistent 3D head stylization from a single style reference image. It builds on a 3D-aware portrait diffusion backbone and injects style through a style-conditioned feature fusion mechanism, preserving identity and head structure while allowing strong artistic transformations.
The framework uses a multi-view portrait diffusion model as its structural prior. Given a content portrait and target camera pose, the backbone provides view-consistent geometry and identity cues across a full 360-degree range.
Separate content and style appearance modules encode identity-related structure and artistic appearance. Style Fusion Attention modulates content keys with style features before shared attention, enabling spatially selective stylization without letting the frozen content pathway dominate.
The style modules are fine-tuned with GAN-generated paired multi-view data. This one-time training stage teaches the model consistent stylization across viewpoints while preserving the realism and identity priors of the frozen content branch.
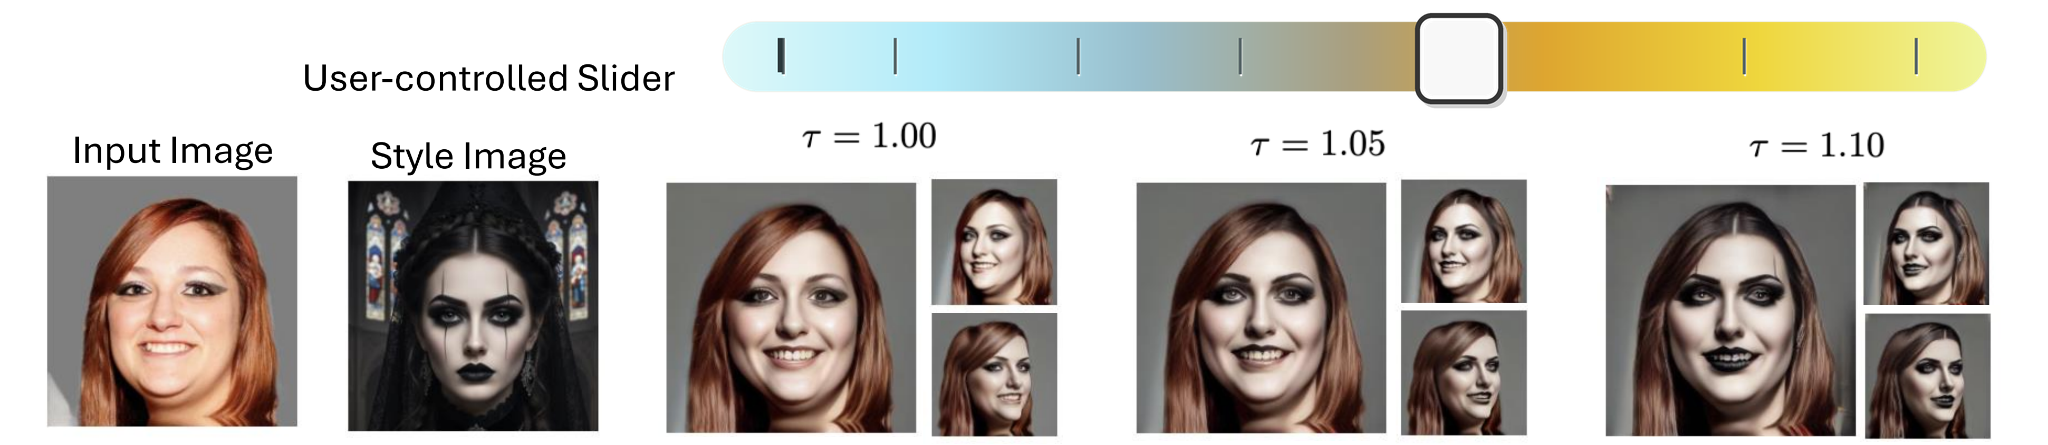
Region masks allow style to be applied to selected areas such as hair, eyes, or mouth, and multiple style references can be fused in one pass. A temperature-based key scaling factor controls stylization strength at inference time.
Controllable stylization intensity. Scaling the style key features with a user-controlled temperature factor adjusts the style strength from subtle edits to stronger stylized outputs while maintaining multi-view consistency.
Qualitative comparisons across methods and styles.